Paper

Self-Retrospection Distillation: Turning Post-hoc Experiences into Prior Foresight

Uses hindsight as a teacher for pre-action foresight, not just action imitation, adding dense supervision when RLVR groups have no reward contrast.

arXiv ↗Oct 6, 2026Code ↗

  • llm
  • nlp
  • reinforcement learning
  • self-distillation
  • agents
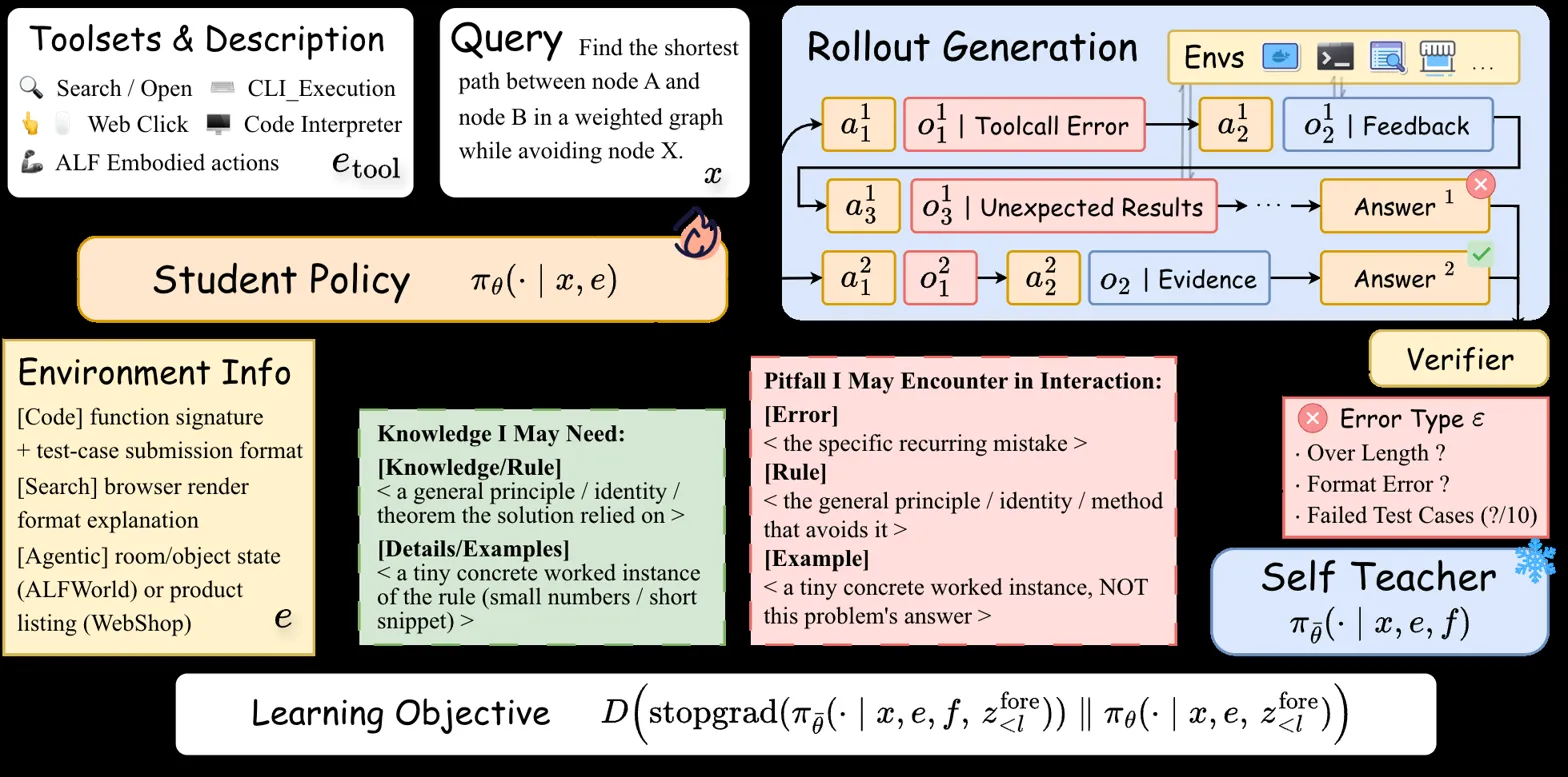
Detailed pipeline showing student policy, rollout, self-teacher, and learning objective method

What it is

Adds a prospective self-distillation target for RL-trained agents: use completed trajectories to teach what the policy should have anticipated before acting. Instead of learning only from reward contrast or hindsight-to-action distillation, SRD distills post-hoc trajectory knowledge into pre-interaction foresight targets, so even reward-uniform failures or successes provide training signal.

Key results

  • Up to +24.2 points over RLVR/self-distillation baselines on 10 tasks
  • At 2B, +SRD gets 60.6% success vs 0.0% for RLVR with same budget
  • 4B GRPO+SRD gains +10.03 Math avg and +8.33 Code avg over GRPO

Shows that post-hoc trajectories can supervise predictive representations before interaction, recovering learning signal when group-relative RL is blind.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.