Paper

Beyond Pixels: From Video Priors to 4D Worlds

Uses final shared-VAE video latents as direct input to a pretrained 4D decoder, bypassing RGB and reusing one checkpoint across text- and image-video DiTs.

arXiv ↗Aug 11, 2026

  • cv
  • 4d generation
  • video diffusion
  • 3d reconstruction
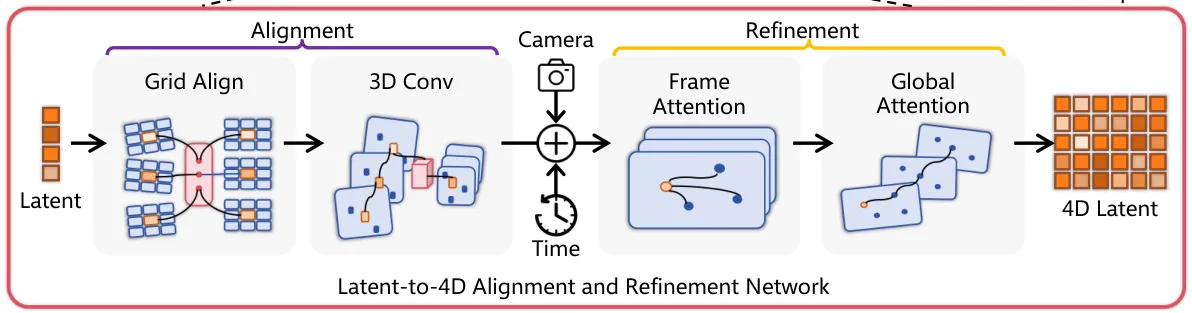
Pipeline diagram showing latent-to-4D alignment and refinement network stages

What it is

Maps final video-model VAE latents directly to dynamic 3D scenes, skipping RGB reconstruction. One trained checkpoint transfers across multiple compatible video generators. Instead of decode-video-then-reconstruct or retraining each generator for geometry, it treats shared final VAE latents as the interface to 4D prediction and learns one latent-to-4D adapter plus refinement stack that works across compatible DiTs.

Key results

  • I4D-200: 61.60 DINO-F1, +5.81 over matched Wan2.2-I2V-A14B+4RC
  • Text4D-200: 57.09 DINO-F1, +2.88 over matched Wan2.1-1.3B+4RC
  • Text4D-200: 57.01 DINO-F1, +3.45 over matched Wan2.1-14B+4RC

Shows shared VAE latents can serve as a reusable geometry interface across compatible video generators without generator-specific 4D retraining.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.