Paper

Recursive Synthesis for Long-Horizon Terminal Tasks

A recursive verified synthesis pipeline that makes terminal tasks harder by extending seed solutions, then aligning tests, instructions, and env before sandbox validation.

arXiv ↗Aug 5, 2026

  • llm
  • agent training
  • synthetic data
  • reinforcement learning
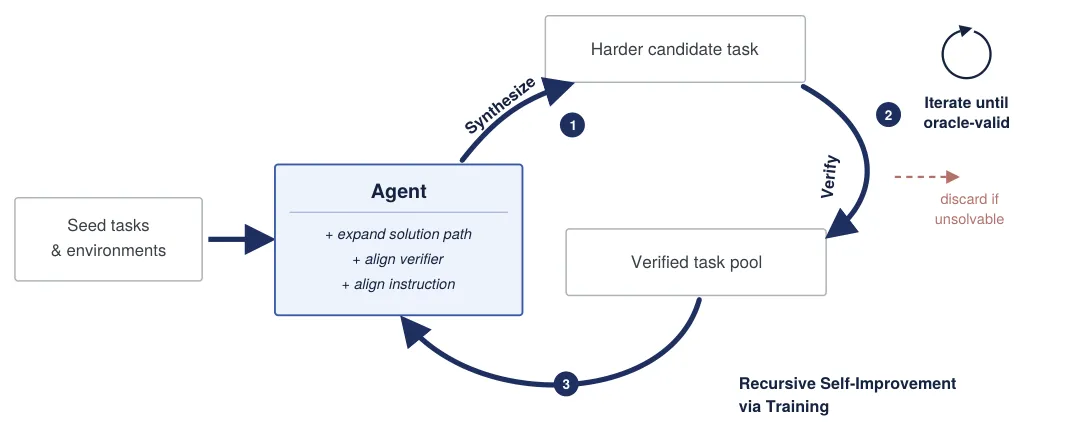
Pipeline diagram showing recursive self-improvement method with synthesize-verify-train loop

What it is

Recursively synthesizes verified long-horizon terminal tasks from seed tasks, scaling executable agent training data cheaply while increasing task difficulty each round. Instead of one-shot task generation that breaks instruction-env-verifier consistency, RST grows verified seed tasks recursively: extend the solution first, then realign verifier, instruction, and environment, validate in sandbox, and reuse accepted tasks as new seeds.

Key results

  • 37,484 verified terminal tasks from 639 seeds at about $0.05 per task
  • DeepSeek-V4-Pro pass@4 drops from 90.0% at R1 to 2.5% at R15
  • PPO lifts Qwen3.5-27B to 49.44%, 32.00%, 22.07% on 3 benchmarks

Verified recursive task growth can scale long-horizon agent data cheaply while continuing to raise difficulty and improve downstream terminal-agent training.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.