
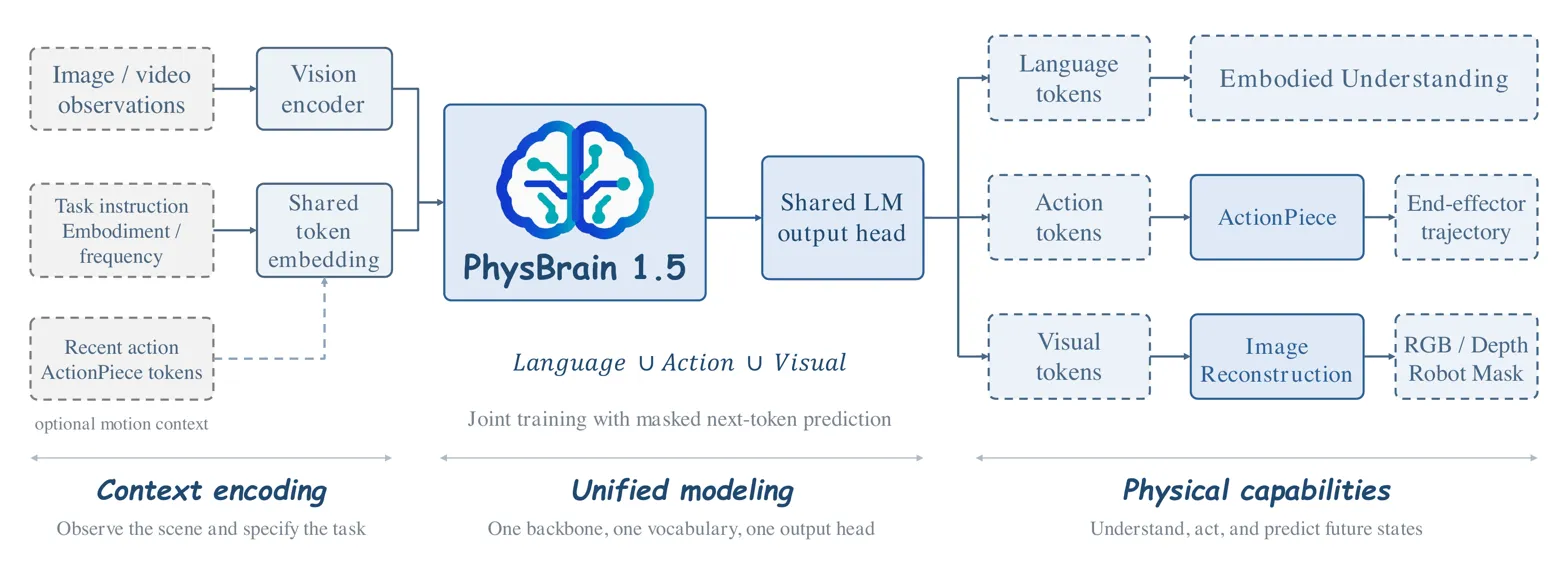
What it is
Extends a VLM into a single autoregressive model for embodied understanding, action generation, and future-state prediction using shared discrete tokens. Instead of separate perception, policy, and world models, it casts language, end-effector motion, and future RGB/depth/mask outputs as one token stream and trains a shared VLM backbone on human-video pretraining plus embodied SFT.
Key results
- 72.5 avg on 28 embodied benchmarks, best open-source overall
- Ranks 1st on 14 benchmarks and 2nd on 10 among open-source models
- Near proprietary models: 72.5 vs GPT-6-Astra 73.3 and Gemini 3.6 Flash 73.0
A shared token-generation interface can jointly learn physical understanding, action, and state prediction without giving up strong embodied benchmark performance.