Paper

PhysEvo: Astra Can Act, Let It

A frozen-model RSI loop that edits robot control, observation, and skills from trajectory evidence, then validates and retains fixes for later tasks.

arXiv ↗Oct 6, 2026

  • robotics
  • llm
  • robot manipulation
  • agentic systems
  • self-improvement
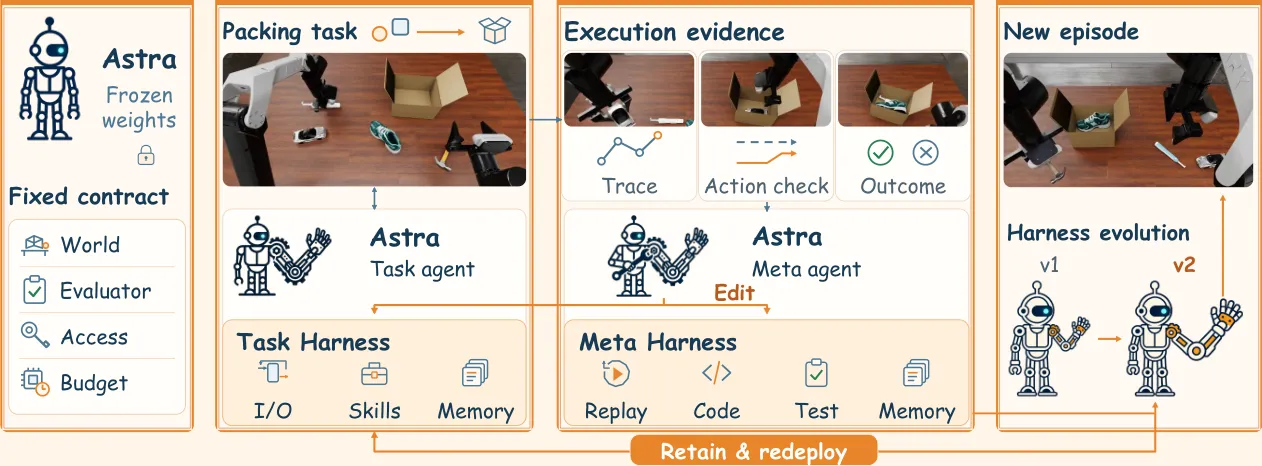
Pipeline diagram showing Astra's task/meta agents, harness evolution, and redeployment loop

What it is

A frozen robot foundation model improves itself by editing its action/observation harness and diagnostic tools from execution traces, instead of updating weights or training a policy. Instead of retraining a robot policy, execution failures are turned into persistent harness edits: the same frozen model acts, diagnoses trajectories, revises tools/skills, tests fixes, and reuses improved diagnostics.

Key results

  • 62.0% success on 42 RoboDojo tasks vs 47.17% for RoboDawn
  • 55.0% success on 8 hard manipulation tasks vs 1.25% direct Astra
  • 84.0% success and 90.6/100 on 5 real-world tasks over 25 trials

Reliable robot behavior can be improved substantially by evolving the harness around a frozen model, not the model weights.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.