
What it is
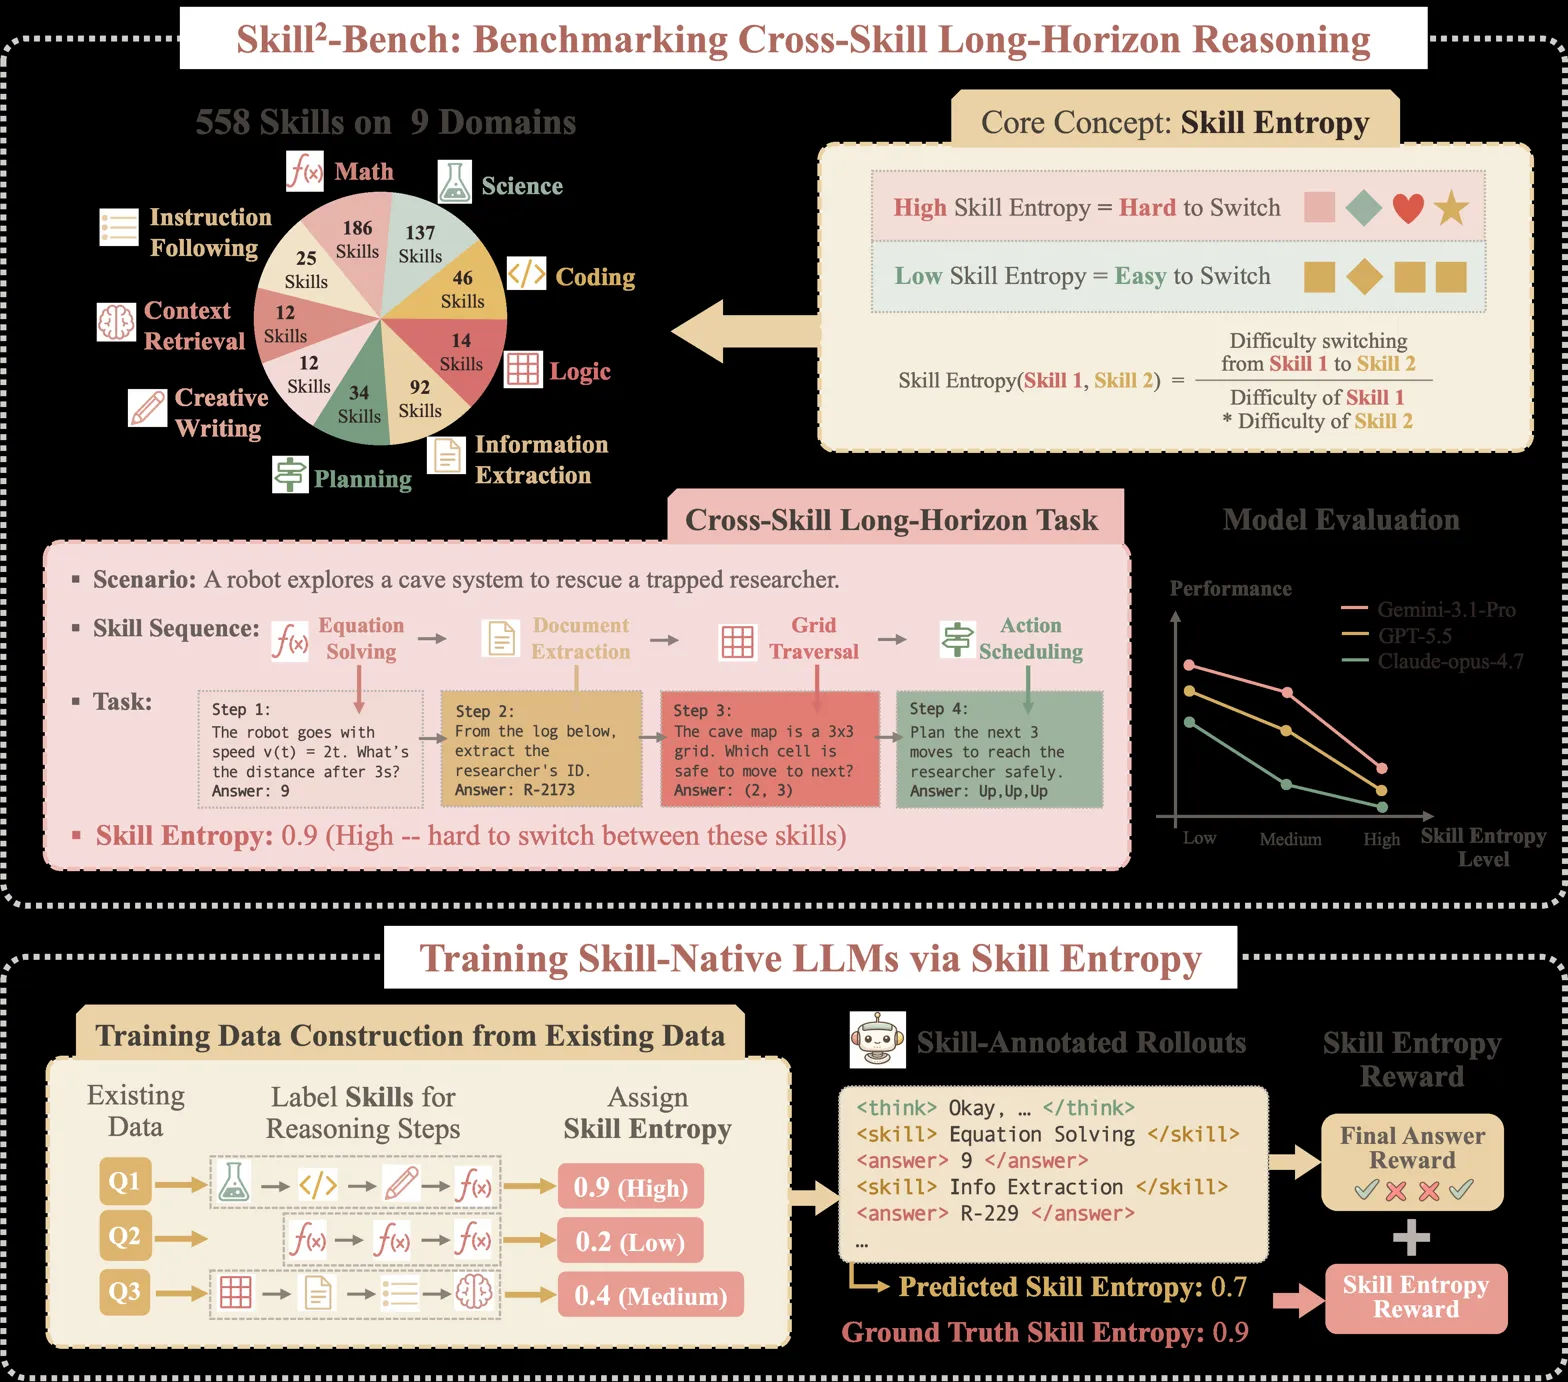
Introduces Skill Entropy to measure skill-switching difficulty in long-horizon reasoning, plus a benchmark and RL training signal that improves cross-skill performance. Instead of scoring isolated skills, measures how hard it is to switch between skills and uses that same signal for RL. The model predicts both step answers and skill labels, rewarding correctness plus alignment to the gold skill sequence.
Key results
- Qwen3-4B-Instruct improves 34.4% -> 68.4% on Skill2-Bench
- Qwen3-1.7B improves 14.6% -> 40.1% on Skill2-Bench
- Cross-skill setting cuts accuracy by 4% to 13% vs single-skill evals
Long-horizon reasoning is bottlenecked by switching between skills, and supervising the skill sequence directly can substantially reduce that gap.