
What it is
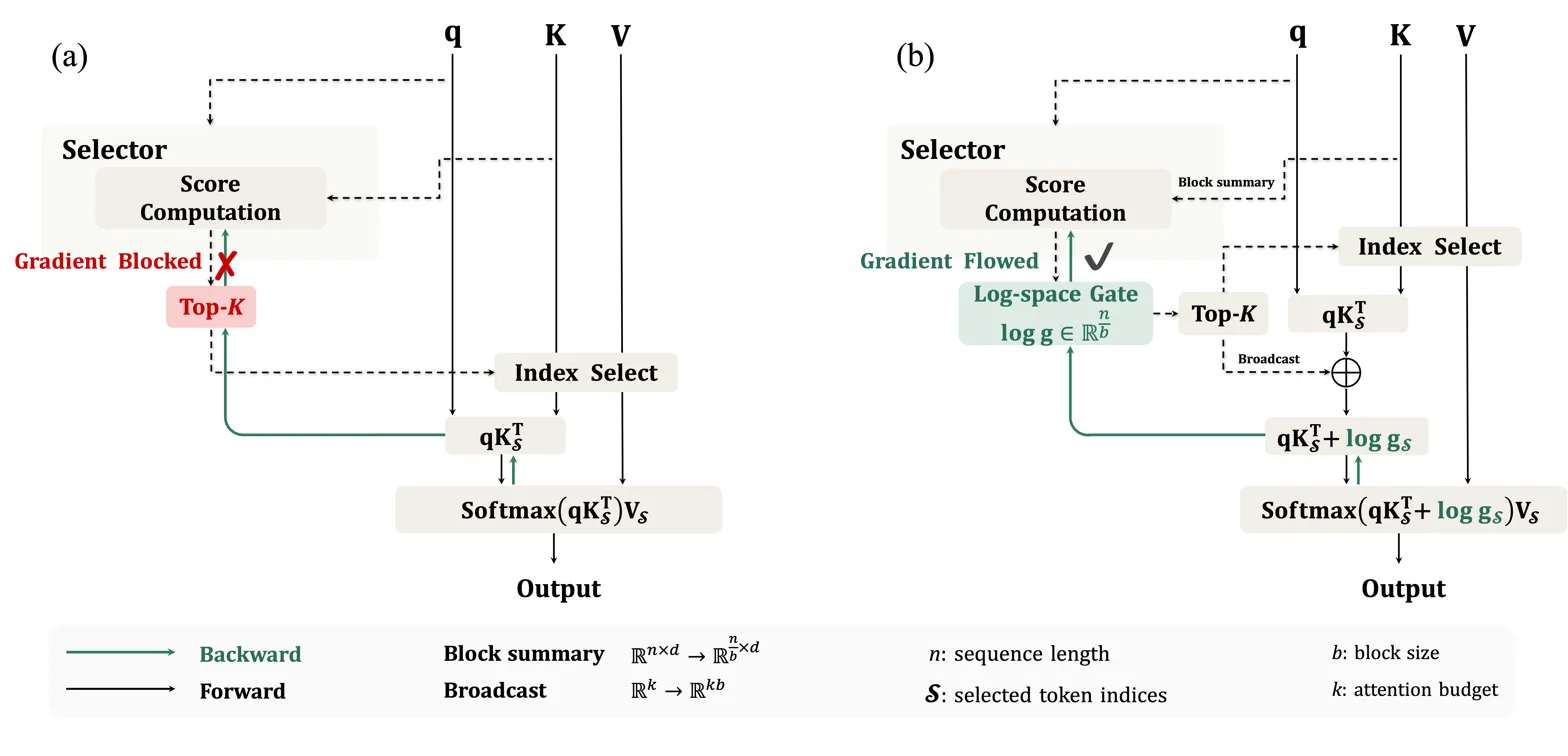
End-to-end sparse attention training for pretrained LLMs by injecting selector scores into attention logits, avoiding distillation and improving context ranking under fixed budgets. Instead of distilling dense attention because Top-K blocks LM gradients, SAS keeps Top-K but adds continuous log-space gates inside attention softmax so the LM loss directly learns which context blocks matter under a budget.
Key results
- At 1024 budget, +10.6 to +15.5 GPQA-Diamond vs SeerAttention-R
- At 1024 budget, +6.0 to +7.7 MATH500 vs SeerAttention-R
- On BFCL, improves by up to +3.5 and nearly recovers full attention at 4096
Directly optimizing context ranking with the LM objective is more effective than matching dense attention, especially when the attention budget is tight.