Paper

Dream-RSI: Recursive Self-Improvement through Evolving Worlds

Uses historical discovery trees as replay worlds to optimize exploration policies offline, then redeploys the improved policy online in a self-improving loop.

arXiv ↗Sep 14, 2026Code ↗

  • nlp
  • llm
  • agents
  • exploration
  • code generation
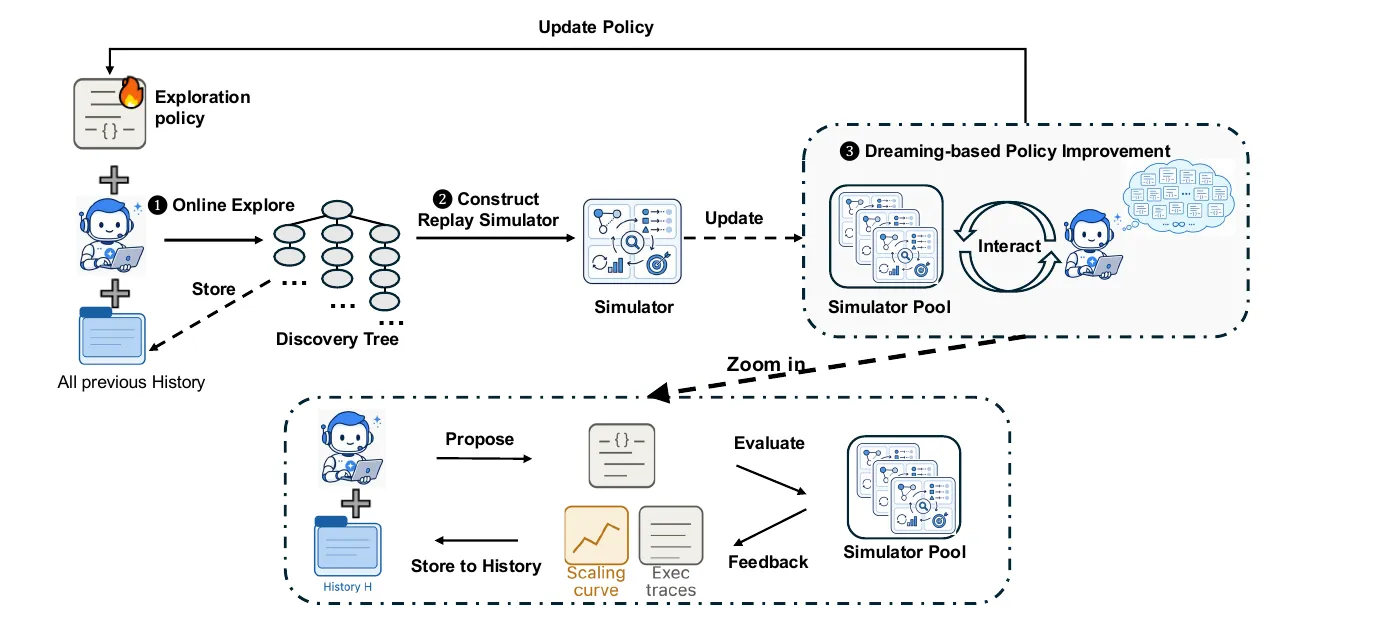
Pipeline diagram showing exploration, simulator, and dreaming-based policy improvement method

What it is

Turns past discovery trees into replay simulators to improve exploration policies offline, then redeploys them online in a recursive self-improvement loop. Instead of fixed exploration or costly online meta-optimization, it replays recorded discovery trees as simulators to score and revise exploration policies off-policy, while keeping the underlying coding agent unchanged.

Key results

  • Lasso: up to 162x fewer agent calls than SimpleTES
  • Math optimization: over 50x budget savings vs SimpleTES within 1k gens
  • KernelBench: up to 2.09x better kernel performance at equal budget

Shows that logged discovery history can act as a cheap simulator for improving long-horizon exploration policies without repeated online rollouts.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.