Paper

4DAnyone: Create Anyone in 4D from a Casual Monocular Video

Packs growing reference views into fixed-cost context and rotates target-view groups during denoising to keep many-view generation consistent for 4DGS.

arXiv ↗Aug 20, 2026Code ↗

  • cv
  • 4d reconstruction
  • novel view synthesis
  • gaussian splatting
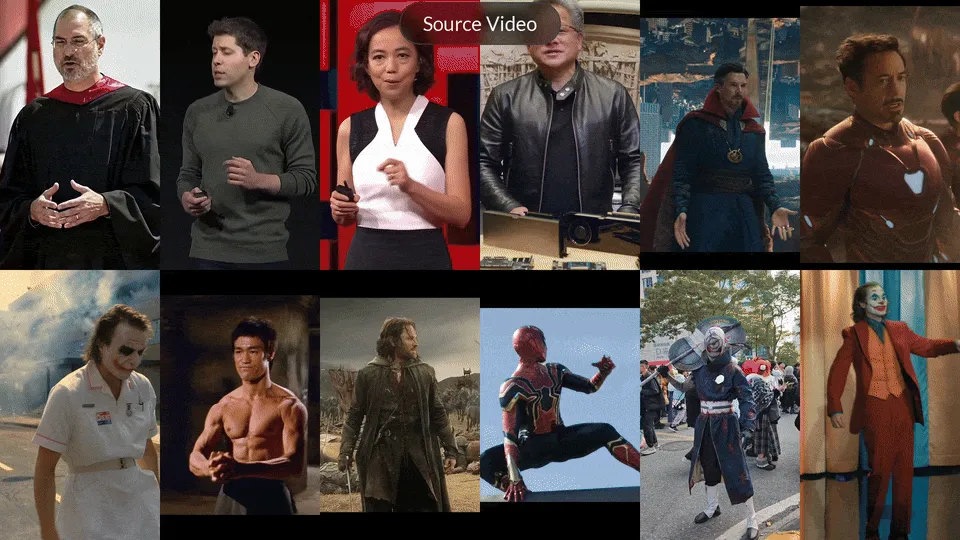
Composite grid showing diverse face/video generation outputs from source video

What it is

Reconstructs 4D humans from a casual monocular video by generating multiview-consistent videos and lifting them into 4D Gaussian Splatting. Instead of denoising many target views in isolated batches, it keeps all prior views as fixed-cost packed context and rotates target-view groups during diffusion to share structure across groups. It uses sparse 3D skeleton conditioning rather than dense depth or known cameras.

Key results

  • Beats prior methods on DNA-Rendering novel-view video quality
  • Beats prior methods on DyMVHumans downstream 4DGS reconstruction
  • Generalizes robustly to in-the-wild monocular videos

Shows that reconstruction-scale multiview diffusion needs both scalable reference conditioning and cross-group target communication, not just camera control.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.