Paper

Co-RL: Unsupervised Reasoning Emerges from Diverse Cohort in Multi-agent RL

Peer-supervised RL replaces self-reward with rewards from independent cohort models. Diverse agents co-train without labels, shared params, judges, or reward models.

arXiv ↗Aug 19, 2026Code ↗

  • llm
  • cv
  • reinforcement learning
  • reasoning
  • vision-language models
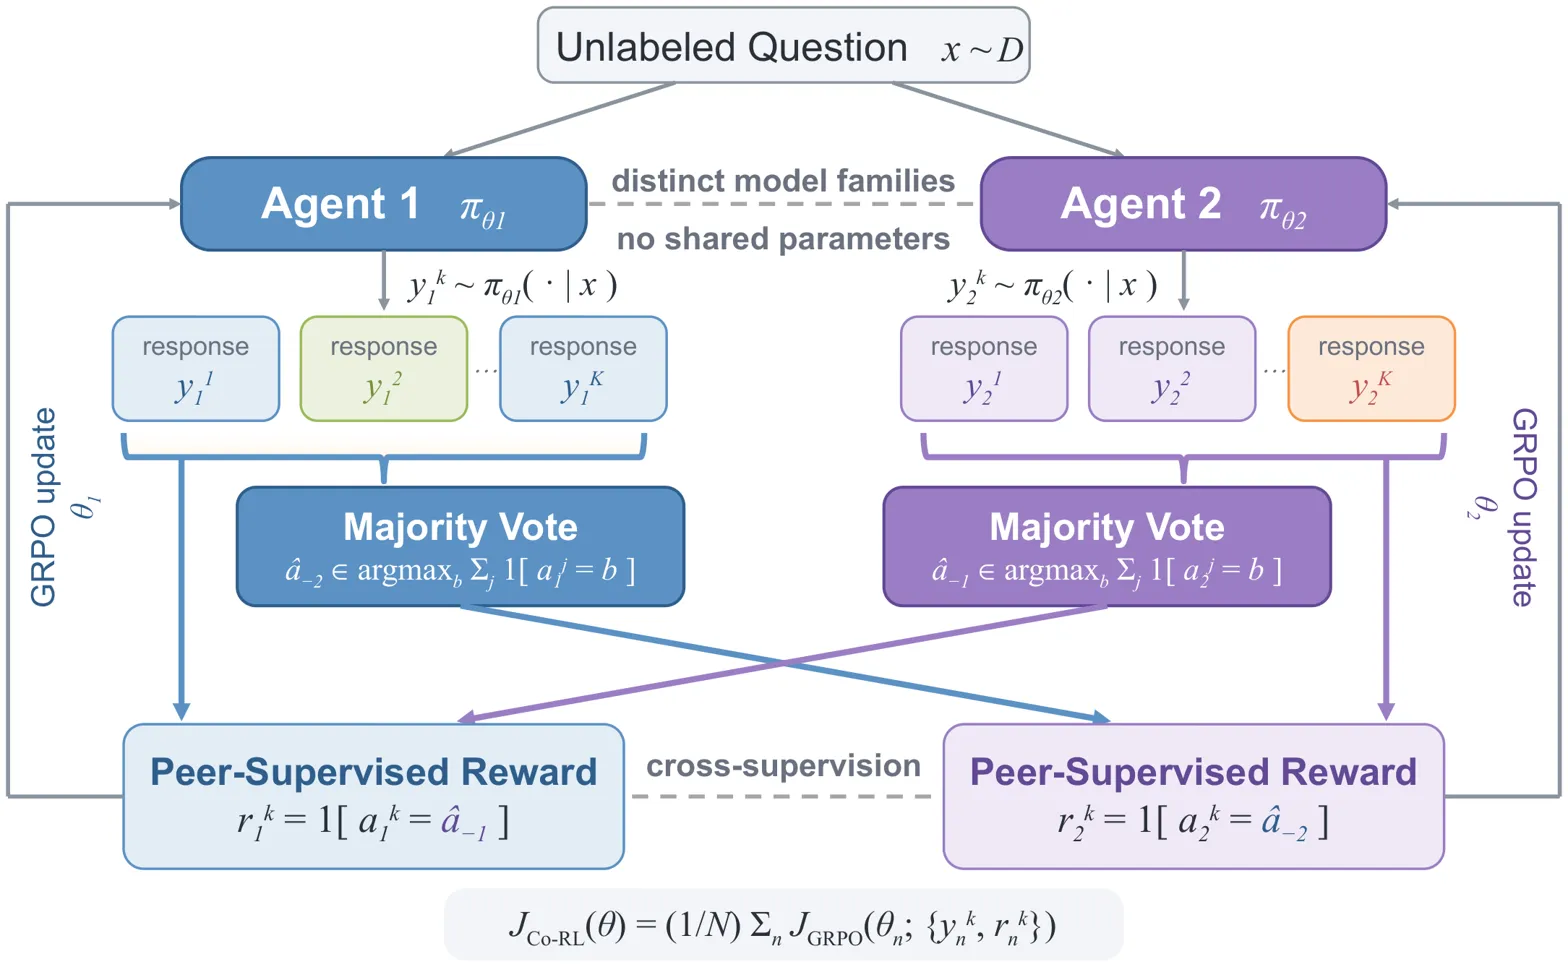
Method pipeline showing co-RL cross-supervision between two agents with peer rewards

What it is

A label-free multi-agent RL framework where decoupled models train on peer-generated rewards, using cohort diversity to avoid self-reinforcing collapse and improve reasoning. Instead of self-rewarding from a model's own votes, decoupled agents reward each other using peer majority-vote pseudo-labels. Diversity across model family, size, and prompt phrasing reduces correlated errors and stabilizes label-free RL.

Key results

  • 3.0-8.6% avg gains on 7 text-only benchmarks over base LLMs
  • 2.3-7.2% avg gains on 4 multimodal benchmarks over base VLMs
  • Beats prior multi-agent RL on CoMAS by 4.0% avg with half the agents

Independent peer rewards plus cohort diversity can turn unlabeled reasoning data into a stable learning signal across LLMs and VLMs.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.