
What it is
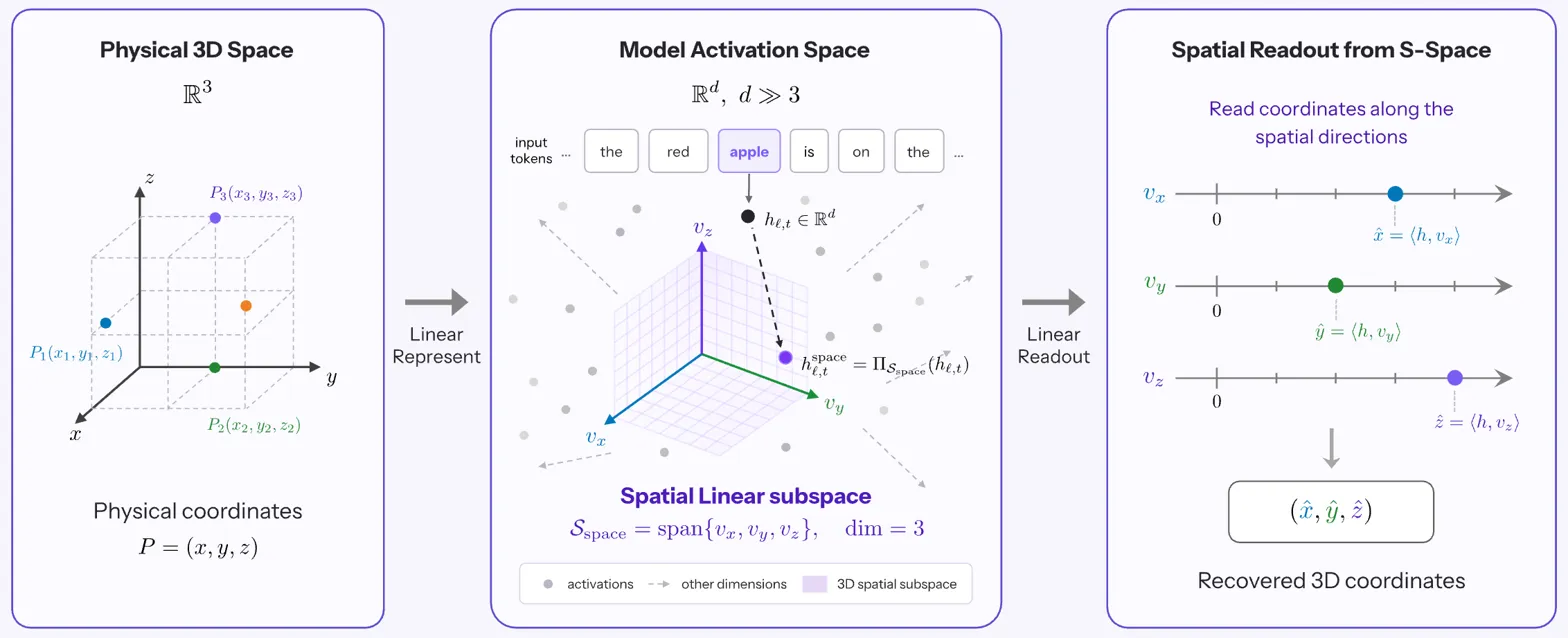
Finds a linear internal spatial subspace in MLLMs where object tokens encode x/y/depth coordinates, and uses it to probe, edit, and diagnose spatial reasoning. Instead of treating spatial behavior as opaque, it exposes a fixed 3D linear workspace in hidden states: object tokens linearly encode left-right, up-down, and depth, readable across prompts and causally editable.
Key results
- 99.31% on SpinBench vs 60.42-72.92% direct generation
- 95.21% vs 60.96% direct on SpinBench for Qwen3.6-27B w/o premise
- S-Space readout is near direct QA: 96.50% vs 97.83% on SpatialTunnel
Shows MLLMs often perceive spatial layouts correctly, but fail mainly in transforming and using those representations across viewpoints.