Paper

SenseNova-U1.5: Towards Native Unified Visual Intelligence

A native unified pixel-space model replaces split understand/generate stacks, then merges task-specialized RL experts through on-policy distillation.

arXiv ↗Sep 10, 2026Code ↗

  • multimodal
  • image generation
  • image editing
  • vision-language models
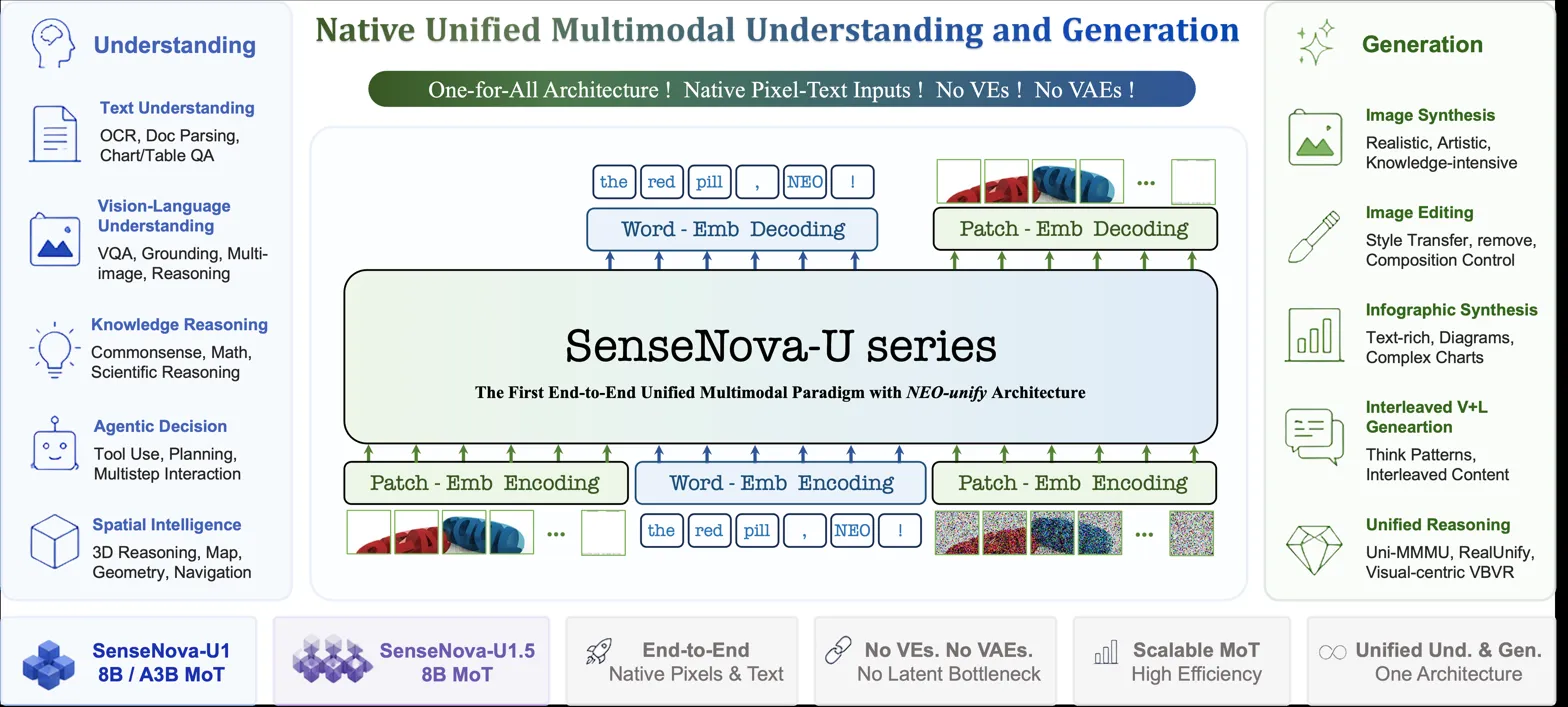
Shows unified multimodal architecture with encoding/decoding pipeline, the core method contribution

What it is

An 8B native unified multimodal model that handles visual understanding, generation, editing, and interleaved creation in one encoder-free, VAE-free system. Instead of separate vision encoders and VAEs, it uses one native pixel-space model with spatially joint patch reconstruction and a specialize-then-unify post-training scheme via RL experts plus on-policy distillation.

Key results

  • Supports native generation at up to 4096×4096 resolution
  • Compresses each 32×32 image region into a single visual token
  • Uses an 8.2B-parameter Mixture-of-Transformers for understanding and generation

A shared native visual representation can transfer multimodal understanding into visual planning, editing, and generation within one end-to-end model.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.