
What it is
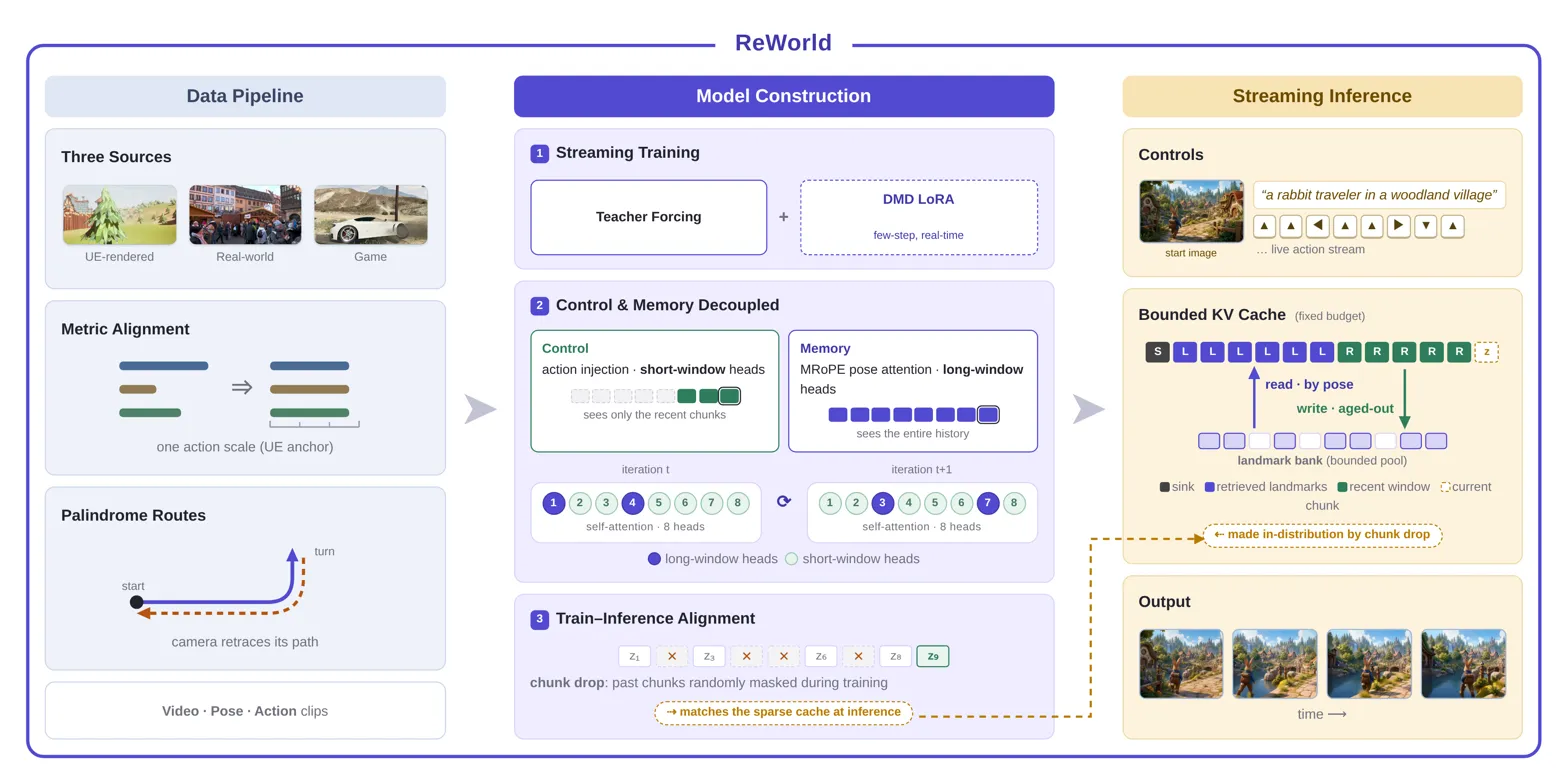
Interactive world model that separates short-horizon control from long-horizon memory, then serves both under a fixed cache for real-time streaming video. Instead of training control and memory in one shared horizon, it splits them by attention window: most heads learn action following on short context, a few learn recall on full history, then pose-retrieved landmarks compress memory into a fixed cache.
Key results
- 11.95° rotation error, best control fidelity among 6 recent baselines
- Best camera-motion consistency and best generation quality in 3-axis eval
- At 64s rollouts, a 12-chunk cache still regenerates the starting view
Long-horizon spatial recall can be retained in interactive video generation without sacrificing control or using an unbounded KV cache.