Paper

EnvHarness: Awakening Static Worlds for Agent Learning

Wraps frozen environments with modular interface-level transforms, then auto-writes them from rollout diagnostics to expose and train specific agent weaknesses.

arXiv ↗Aug 20, 2026Code ↗

  • llm
  • agent learning
  • environment generation
  • reinforcement learning
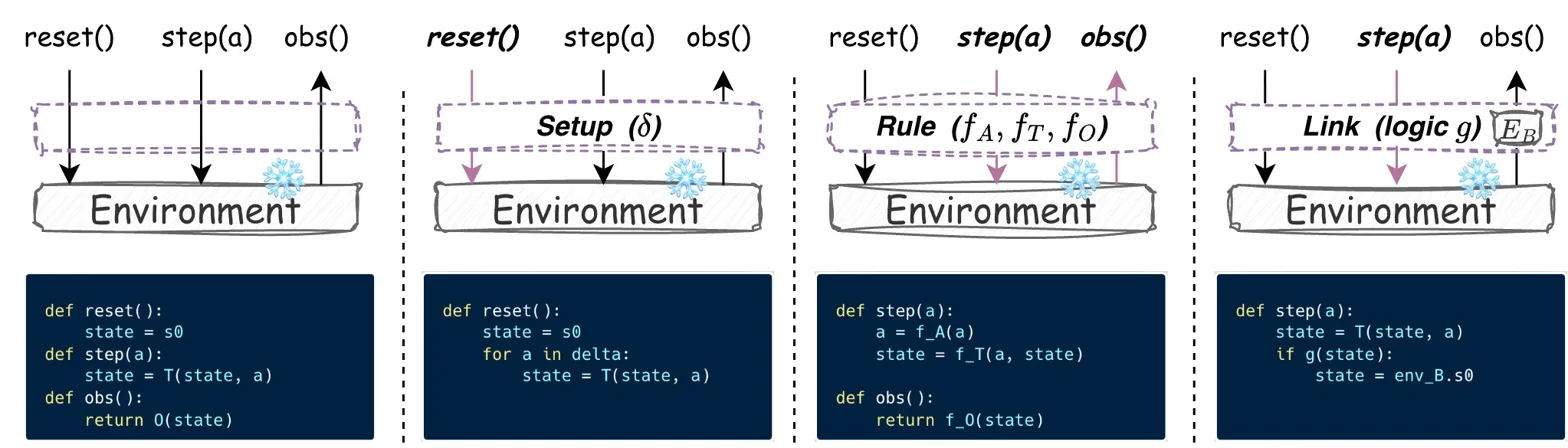
Method diagram showing environment interface with code mappings for reset/step/obs abstraction

What it is

Wraps static agent environments with modular interface-level components, then auto-customizes them from rollout failures to target policy weaknesses. Instead of generating new domain-specific environments, it wraps existing ones with plug-in state, interface, and task-composition transforms; a black-box rigger writes and validates these wrappers from agent rollouts while keeping the original verifier.

Key results

  • Up to +9.0 points on held-out tasks vs original/generated envs
  • 9.8% fewer execution steps while improving performance
  • Up to +6.5 points in RL over learning in original environments

Targeted interface-level reshaping of existing environments can beat both static training worlds and domain-specific environment generation.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.