Paper

ZGCM-1: A Fully Open and Extremely Efficient Foundation Model for Math and Agentic Search

A compact-model recipe that trades brute-force scale for long-context reasoning and tool use, using hybrid attention, FP8+Muon training, and MDP supervision.

arXiv ↗Sep 11, 2026Code ↗Dataset ↗

  • llm
  • reasoning
  • long-context
  • tool-use
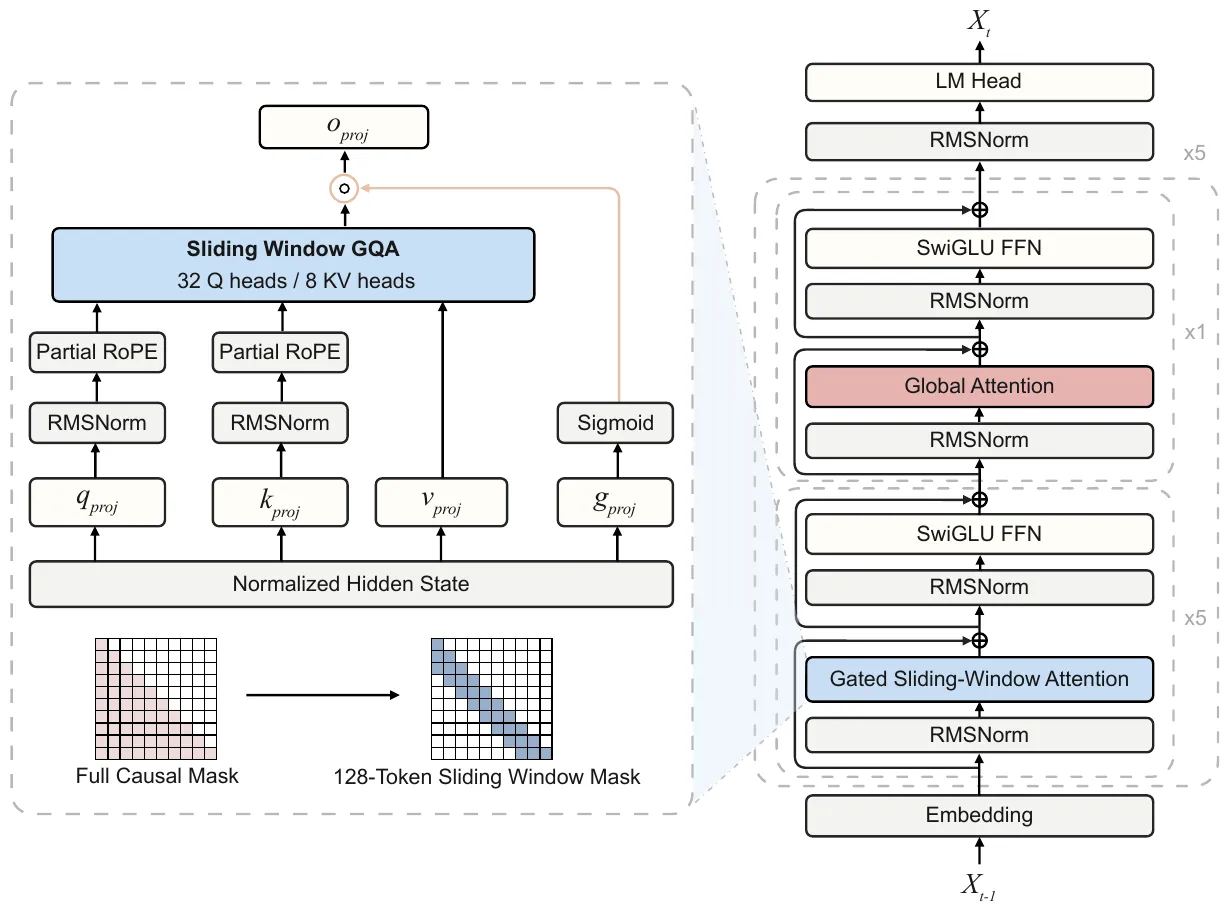
Detailed model architecture diagram showing attention mechanism and layer structure

What it is

An open 7B foundation model for math and agentic search, trained from scratch with a highly efficient 256K-context recipe and released with code, data, and checkpoints. Instead of scaling parameters, it makes a compact 7B model competitive via deliberate reasoning plus tool use, enabled by an efficient open recipe: hybrid sliding-window/global attention, FP8+Muon pretraining, and MDP-style mid-training on interaction traces.

Key results

  • 1st average rank across 14 reasoning benchmarks among 7B-8B models
  • 97.1% on MATH-500 and 75.0% on AIME 2026
  • ~4.2x 16K pretraining time-to-loss vs BF16/AdamW baseline

Shows that a fully open 7B model can stay competitive on hard math and agentic search by combining efficient long-context training with explicit tool-oriented supervision.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.