Paper

On-Policy Self-Distillation without Any Supervision

Uses rollout consensus as pseudo supervision instead of GT labels, then distills onto the model's disagreeing trajectories with dense token-level targets.

arXiv ↗Aug 9, 2026Code ↗

  • llm
  • reasoning
  • self-distillation
  • post-training
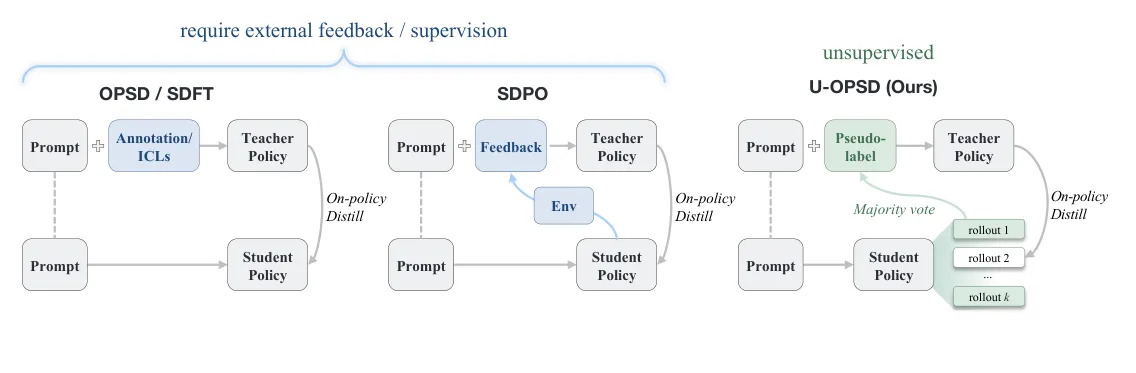
Method pipeline comparing OPSD/SDFT, SDPO, and proposed U-OPSD approach

What it is

Unsupervised on-policy self-distillation for LLM reasoning: the model builds pseudo-solutions from rollout consensus and distills corrections on disagreeing traces. Removes gold answers and external teachers from on-policy self-distillation: majority-voted self-consistent rollouts become the teacher context, and only disagreeing completions are corrected with token-level distillation.

Key results

  • Qwen3-8B non-thinking: 54.31 avg, +10.7 over base and +2.3 over OPSD
  • Qwen3-4B non-thinking: 49.49 avg, +8.5 over base and +3.2 over OPSD
  • Thinking mode beats GRPO by 0.7% at 4B and 1.1% at 8B on avg

Shows that internal consistency can supply enough privileged context for effective on-policy self-distillation without external supervision.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.