Dataset

CrawlSinger-OS

Contains 2,317 hours of Mandarin singing clips from 4 public sources with audio plus lyrics, MIDI pitches, note tokens, alignment, and BPM for singing tasks.

Hugging Face ↗Jul 30, 2026Paper ↗Code ↗

  • audio
  • singing-voice-synthesis
  • music-score
  • mandarin
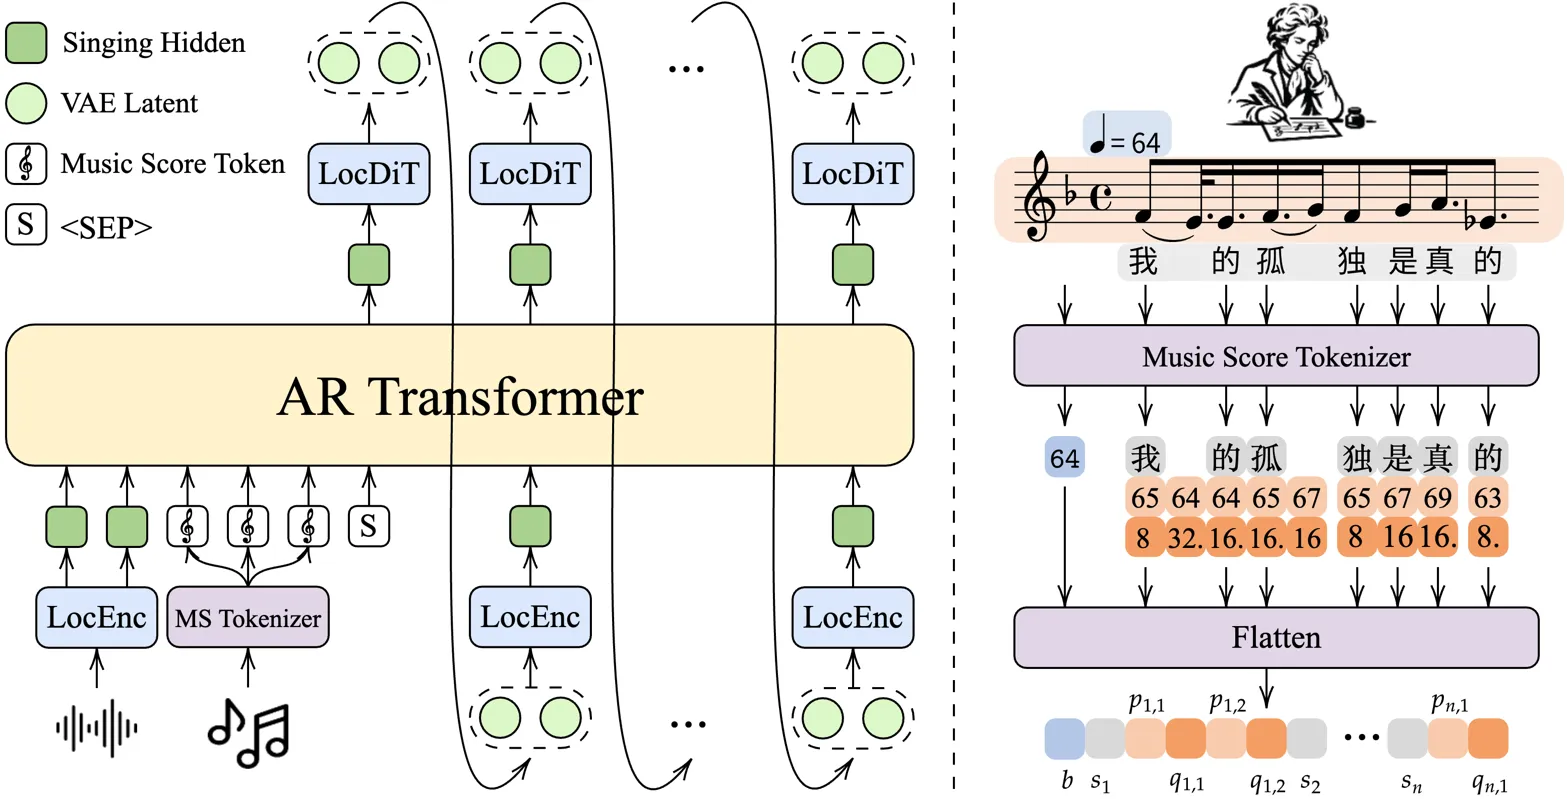
Shows AR Transformer pipeline with music score tokenizer and VAE latent generation

What it is

Open-source singing corpus with 2,300+ hours of audio and unified lyric-note-score annotations for score-native singing synthesis. 2,317 hours and 776k singing segments from 4 public sources, mixing synthetic and real songs with unified lyrics, MIDI pitch, note values, lyric-to-note alignment, tempo, and audio.

Key results

  • 2,317 hours across 776k segments
  • 4 sources: synthetic + real singing
  • MIT license; complete repo is ~110.4 GB

Useful for training and evaluating score-conditioned singing voice synthesis with lyric-to-note alignment.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.