
What it is
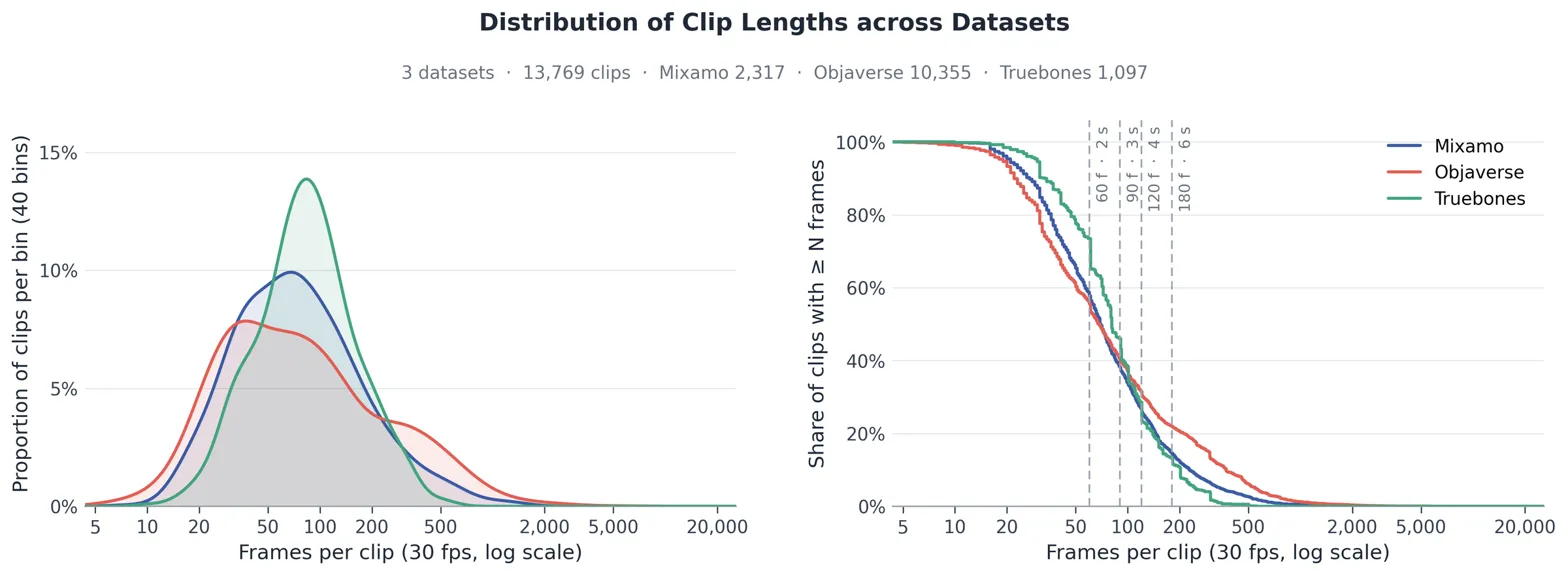
A 13.8K-clip text-paired 3D motion dataset unifying humanoid, animal, and object skeletons with topology and joint annotations. 13,769 motion clips and 7,430 skeletons from Mixamo, Truebones, and Objaverse-XL, unified into one canonical layout with captions, cleaned joint names, body-plan labels, and facing-direction annotations.
Key results
- 13,769 clips and 7,430 skeletons
- 2,001,312 frames at 30 fps, about 18.5 hours
- 3 sources; joints per skeleton range from 3 to 140
Useful for training and evaluating text-to-motion models that must generalize across very different skeleton topologies.