
What it is
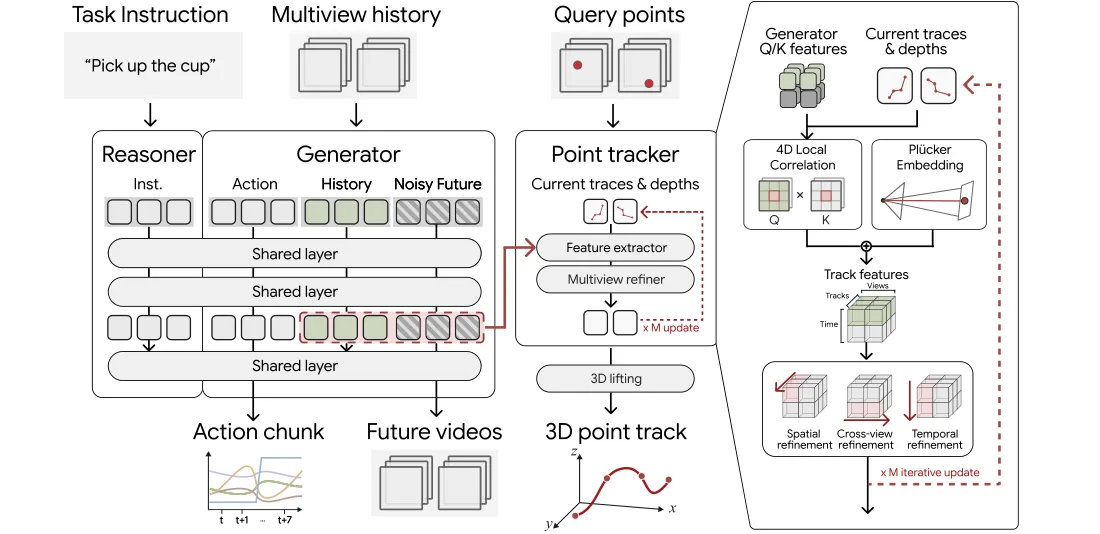
A multi-view world model that jointly predicts future videos and persistent 3D point trajectories, using point-motion supervision to improve 4D forecasting and robot control. Instead of video-only forecasting or per-frame geometry targets, it jointly predicts future videos and persistent 3D point tracks across views, anchoring appearance changes to shared 3D motion and extending the same backbone to action prediction.
Key results
- VP-WorldBench robot: FVD 67.35 vs 78.52 for VPM video-only
- VP-WorldBench general: FVD 81.92 vs 101.37 for VPM video-only
- CMU Panoptic: FVD 128.64, δ3Davg 42.03 vs 150.63, 34.72 for VPM video-only
Persistent 3D point-track supervision makes multi-view future video prediction more geometrically coherent and visually accurate.